Hard caps, no surprise invoices
Pre-consume billing reserves the budget before the request runs, settles on actual cost, and refunds the difference atomically. No race conditions, no overruns, no firefighting after a runaway loop.
Eight cost primitives
All on by default. Configure caps and pricing in the console; the gateway enforces them at request time.
Pre-consume + settle
We quote a price upper bound, reserve from the user's balance, run the request, then settle the actual cost and refund the difference atomically. No race condition between billing and metering.
Multi-window quotas
Per-minute / hour / day / week sliding-window counters across tenants, teams, and individual API tokens. Hit the cap and we 429 with a clear retry-after — no surprise bills.
Custom price tables
Per-tenant pricing overrides. Apply a flat markup, mix in your own discounted contract rates, or zero out a model entirely. Resellers package their own price points without touching upstream rates.
Channel budgets
Cap monthly spend per upstream channel. Alerts at 75% / 90% / 100%. When the cap hits, the router auto-skips that channel and falls back — your wallet survives even when prompts misbehave.
One itemized invoice
Whether you call OpenAI, Bedrock, Anthropic, or Vertex — one consolidated bill. Per-developer / per-team / per-model breakdown. Export CSV for your finance team without log-grepping.
Vouchers & top-ups
Top up via card or ACH; redeem voucher codes for promotions; manual admin adjustments for goodwill credits. Every credit lands as an immutable balance_transactions row.
Daily ledger fold
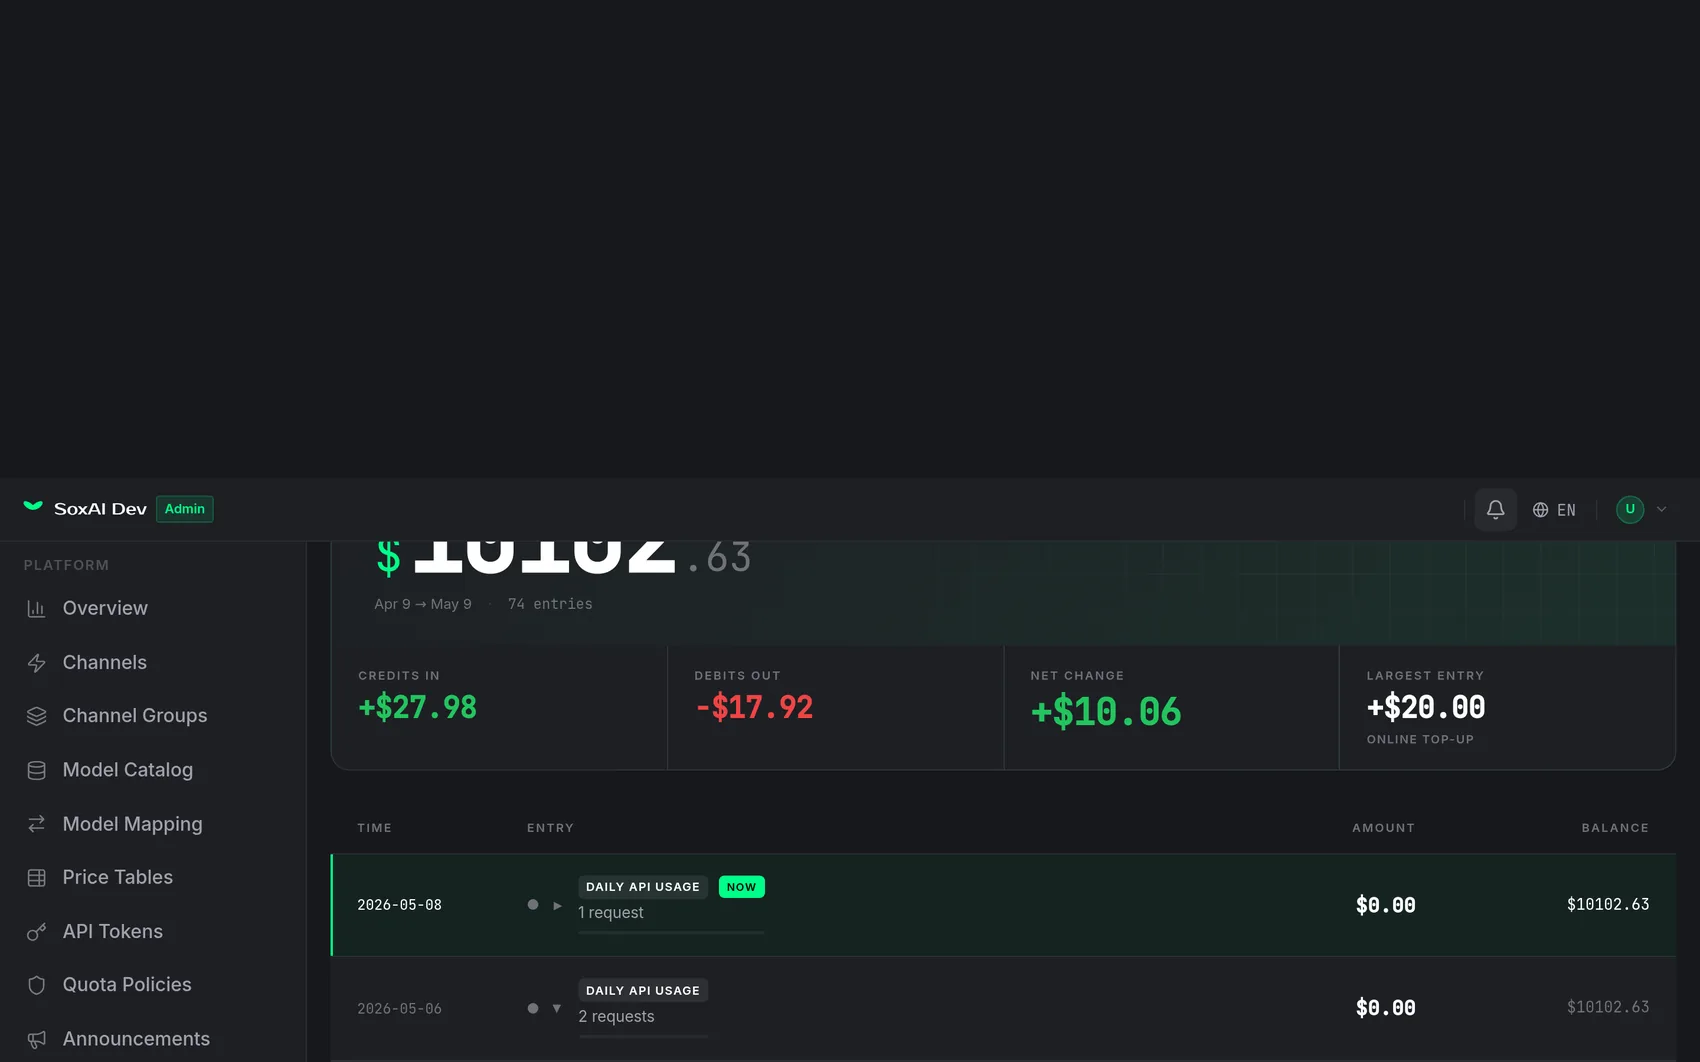
Per-day consumption aggregates with click-to-expand request detail (model, input/output tokens, cost, status). 30 days, 90 days — never a flat list of 5000 rows.
No double-charge invariant
Settle is atomic with refund. If the upstream call errors after pre-consume, we refund the full reservation. Property-tested across dozens of fallback / 5xx / connect-error scenarios.
30 days at a glance — never a flat list of 5,000 rows
Per-day consumption aggregates with click-to-expand request detail: model, input/output tokens, cost, status.
What it solves
Stop runaway loops
An engineer's bug fires 100k requests in an hour. Your team-level quota caps it at 10k/hr. Nothing leaks past your budget — they get a clear 429 and fix the loop.
Multi-team budget split
Marketing has $5k/month. Engineering has $15k. Each team's quota policy enforces its own cap; one team's spike doesn't starve the other.
Reseller markup
Set GPT-4o input from $2.50/M to $4.00/M for your enterprise customers. Their downstream invoice shows your rate; the cost diff is your margin.